Local-AI Social Media Factory
A zero-API-cost marketing pipeline running Llama 3.1 and Stable Diffusion locally — from caption to branded visual to Telegram-approved Facebook/Instagram publish.
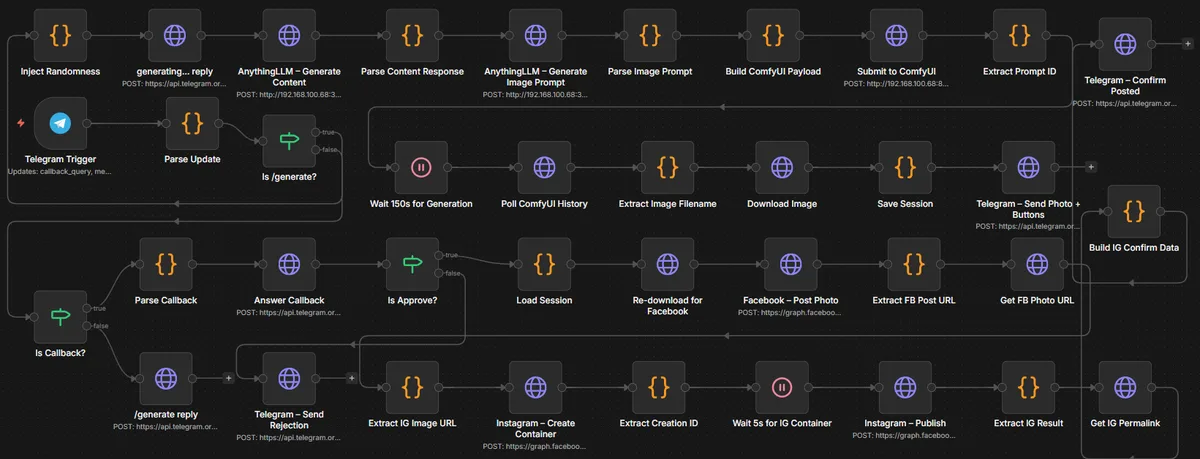
Repo: https://github.com/jerohalili/content-creation-ai-automation Self-hosted GPU system — no public demo; runs on your own hardware via Docker.
The Challenge
Small businesses and marketing teams face a brutal trade-off: either pay compounding subscriptions (OpenAI + Midjourney + Zapier) or do the content treadmill manually — writing captions, designing graphics, publishing, chasing approvals. For agencies handling many clients, the “API tax” destroys margins.
The Solution
I built the Local-AI Social Media Factory on one economic principle: high upfront hardware cost → near-zero long-term operational cost. Local LLMs handle copywriting, local diffusion models handle visuals, n8n orchestrates the flow, and a human approves everything in Telegram before it reaches Facebook or Instagram. No proprietary strategy ever leaves your server.
Technical Highlights
Four-Stage Pipeline
- Synthesis: Caption and promo copy via Llama 3.1 (8B Q8) served through AnythingLLM.
- Visualization: Brand-consistent visuals via ComfyUI + SDXL / Z Image Turbo with custom workflows.
- Verification: Telegram bot sends draft (image + caption) for one-tap approve / regenerate / edit.
- Publishing: Approved content goes to Facebook and Instagram through connected APIs.
The “Mara” Persona Engine
- Sensory hooks: Grabs attention in the first three words.
- Local compliance: References BIR, SSS, PhilHealth to build trust in the Philippine market.
- Zero-fluff filter: Strips robotic idioms;
scripts/parse-utils.jscleans model output.
GPU & Deployment Engineering
- Optimized for RTX 3060 (12GB) minimum, RTX 4070+ recommended, using quantized GGUF models and Docker resource caps.
- Docker Compose for portability;
host.docker.internalfor container-to-host LLM/image callbacks; Ngrok or Cloudflare Tunnel for Telegram webhooks.
System Architecture
| Layer | Technology | Role |
|---|---|---|
| Orchestration | n8n (Docker) | Imports workflows/TechnoByte_CubicPayroll_FB_IG_Content_Generator_v6.json or Guest_FB_Content_Generator_v6.json. |
| LLM Inference | Llama 3.1 8B Q8 via AnythingLLM | Caption generation and post formatting. |
| Image Engine | ComfyUI + SDXL / Z Image Turbo | Custom brand workflows for marketing visuals. |
| Gateway | Telegram Bot API + Ngrok/Tunnel | Approval loop and remote control. |
| Publishers | Facebook + Instagram APIs | Final distribution. |
Impact & Key Takeaways
- 90% reduction in content creation time; zero API fees for text and image generation; 100% data sovereignty.
- Learned local LLM deployment, diffusion workflow tuning, VRAM management, and why human-in-the-loop is non-negotiable for brand safety.
Roadmap
- Short-Term: Better analytics tracking and more platform integrations.
- Medium-Term: Multi-client support with content scheduling dashboard and CRM integration.
- Long-Term: White-label SaaS for local marketing firms with multi-language support.
How to Run This Project
git clone https://github.com/jerohalili/content-creation-ai-automation.git
cd content-creation-ai-automation
docker-compose up -d- Start ComfyUI, link your custom workflow API to n8n.
- Start AnythingLLM, link your local LLM API to n8n.
- Open n8n at
http://localhost:5678, import the v6 workflow JSON, connect the Telegram bot (use Ngrok/Cloudflare Tunnel for webhooks). - Customize prompts in
prompts/and publish — approve posts from Telegram.